Video
Wan-2.1 Pro Text-to-Video Variants: 6
≈ $0.80
800 API credits
No matches. Try “video”, “FLUX” or “webhooks”.
Loading models…
wan-flf2v
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.com/v1/run/wan-flf2v?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
    "image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
    "end_image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg"
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.com/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.com/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/wan-flf2v?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
"end_image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg"
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.com/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
"end_image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/wan-flf2v", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"])# 1. Connect once (Claude Code; Cursor, VS Code, Claude Desktop: https://doitong.com/developers/docs/mcp)
claude mcp add --transport http doitong-models https://api.doitong.com/v1/mcp \
--header "Authorization: Bearer $DOITONG_API_KEY"
# 2. Your agent calls the "run" tool with:
{
"model_id": "wan-flf2v",
"input": {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
"end_image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg"
}
}Call the Wan-2.1 First-Last-Frame-to-Video model (wan-flf2v) through the Doitong API. Docs for agents: https://doitong.com/developers/models/wan-flf2v.md
POST https://api.doitong.com/v1/run/wan-flf2v?wait=20
Authorization: Bearer $DOITONG_API_KEY
Content-Type: application/json
{
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
"end_image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg"
}
If the response status is "queued" or "running", poll GET https://api.doitong.com/v1/requests/REQUEST_ID?wait=20 until it is "succeeded"; the files are in outputs[].url. POST https://api.doitong.com/v1/quote/wan-flf2v with the same body returns the exact price before the run.This request: $0.40 400 API credits Run it on this page
Your new API key. It is shown only now and is already in the code and in the API key field below. Keep it secret: never put it in code that runs in a browser.
Public works made with Wan 2.1 by the Doitong community. Reuse a prompt in one click.
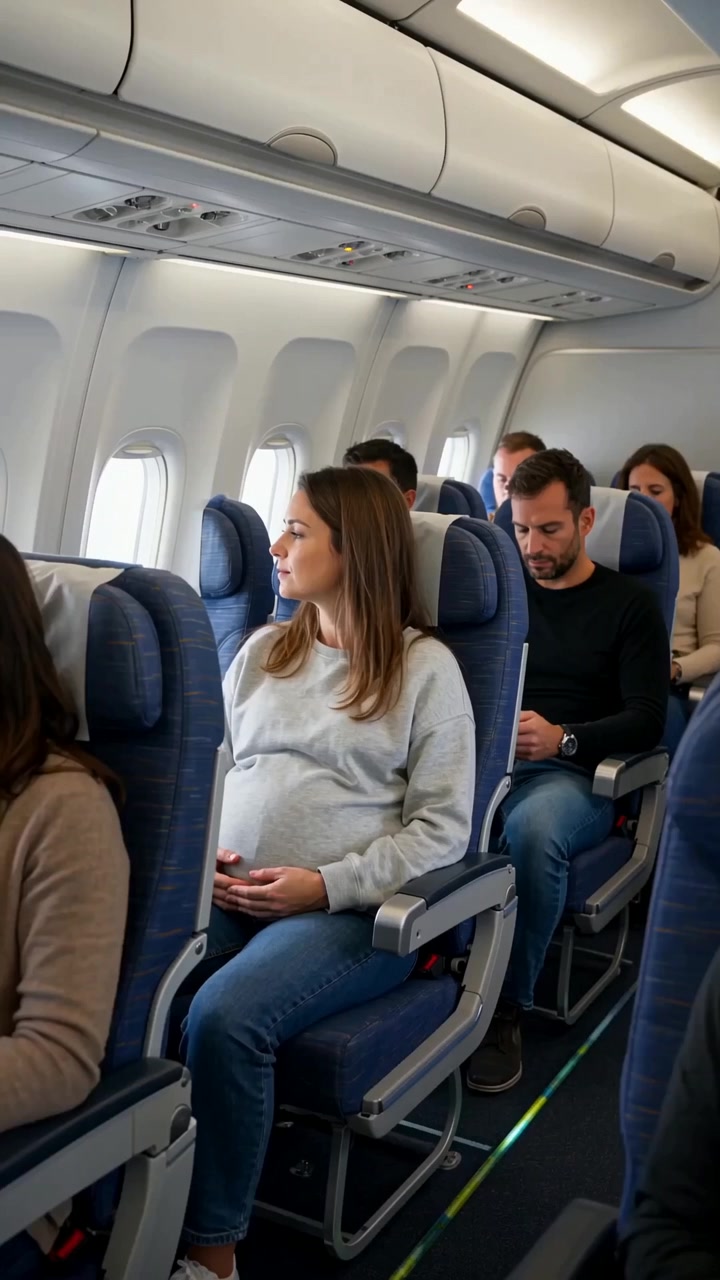 Video
Create a realistic cinematic UGC-style commercial video, exactly 30 seconds long. The entire scene takes place inside a modern passenger airplane during a daytime flight. Natural smartphone-like cinematography, realistic airplane cabin, authentic passengers, natural lighting, realistic skin...
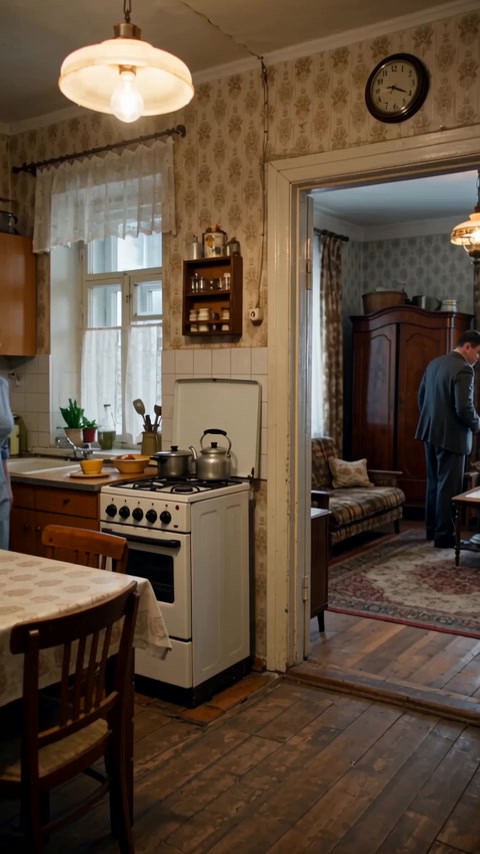 Video
Реалистичная бытовая сцена в советской одесской квартире зимним вечером. Женщина находится на кухне, мужчина — в комнате и прихожей. Атмосфера обычной советской семьи перед приходом гостей. Голоса: все персонажи говорят по-русски с естественным, выразительным одесским говором. Характерная...
Controls are generated from the model schema. The code and the price update as you change them.
/run/wan-flf2v?wait=20
quote → $0.40
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.com/v1/run/wan-flf2v?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
    "image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
    "end_image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg"
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.com/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.com/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/wan-flf2v?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
"end_image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg"
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.com/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
"end_image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/wan-flf2v", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"]){
"jsonrpc": "2.0",
"id": 1,
"method": "tools/call",
"params": {
"name": "run",
"arguments": {
"model_id": "wan-flf2v",
"input": {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
"end_image": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg"
},
"wait_seconds": 20
}
}
}Your key stays in this browser: it is sent only to the Doitong API and saved (localStorage) only if you tick Remember. Get an API key
Creates a clip that moves from `start_image_url` to `end_image_url`, guided by a `prompt`. Resolution is 480p or 720p, aspect ratio auto, 16:9, 9:16 or 1:1. `num_frames` is 81-100 and `frames_per_second` 5-24. Supports a `negative_prompt`, `seed`, guidance and step controls, and LoRA weights through `loras`.
Send either the canonical name or the native name, not both. Canonical names
promptrequired
negative_promptoptional
start_image_urlrequired
image
end_image_urlrequired
end_image
num_framesoptional
frames_per_secondoptional
seedoptional
resolutionoptional
num_inference_stepsoptional
guide_scaleoptional
shiftoptional
enable_safety_checkeroptional
enable_prompt_expansionoptional
accelerationoptional
aspect_ratiooptional
lorasoptional
loras[].pathrequired
loras[].weight_nameoptional
loras[].scaleoptional
File parameters take a public https:// URL, a data: URI up to 10 MB, or the file_url of an upload. Files
{
  "id": "req_8k2m4q7x1z9c3v5b6n0p2r4t",
  "object": "request",
  "model": "wan-flf2v",
  "status": "succeeded",
  "created_at": "2026-10-20T12:00:00Z",
  "started_at": "2026-10-20T12:00:02Z",
  "completed_at": "2026-10-20T12:00:09Z",
  "queue_position": null,
  "cost": {
    "credits": 400,
    "usd": "0.40",
    "charged": 400,
    "refunded": 0
  },
  "input": {
    "prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
    "start_image_url": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg",
    "end_image_url": "https://content.doitong.com/images/showcase/v3/gen_fox_cartoon.jpg"
  },
  "output": {
    "video": {
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.mp4",
      "content_type": "video/mp4",
      "file_name": "0-output.mp4",
      "file_size": 1843200
    },
    "seed": 42
  },
  "outputs": [
    {
      "type": "video",
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.mp4",
      "content_type": "video/mp4",
      "file_size": 1843200,
      "width": 1280,
      "height": 720,
      "duration": 5,
      "stored": true
    }
  ],
  "error": null,
  "metrics": {
    "inference_seconds": 6.8
  },
  "urls": {
    "self": "https://api.doitong.com/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t",
    "cancel": "https://api.doitong.com/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t/cancel"
  }
}
For AI agents: this page as Markdown is at https://doitong.com/developers/models/wan-flf2v.md. All models and guides: https://doitong.com/developers/llms.txt