Image
Wan · v2.2 A14b · Text to Image Variants: 5
$0.025 / image
25 API credits / image
No matches. Try “video”, “FLUX” or “webhooks”.
Loading models…
wan/v2.2-14b/speech-to-video
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.com/v1/run/wan/v2.2-14b/speech-to-video?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
    "image": "https://content.doitong.com/images/showcase/v3/avatar/talking_avatar.jpg",
    "audio": "https://content.doitong.com/audio/showcase/v3/tools/dub_es.mp3"
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.com/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.com/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/wan/v2.2-14b/speech-to-video?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/avatar/talking_avatar.jpg",
"audio": "https://content.doitong.com/audio/showcase/v3/tools/dub_es.mp3"
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.com/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/avatar/talking_avatar.jpg",
"audio": "https://content.doitong.com/audio/showcase/v3/tools/dub_es.mp3",
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/wan/v2.2-14b/speech-to-video", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"])# 1. Connect once (Claude Code; Cursor, VS Code, Claude Desktop: https://doitong.com/developers/docs/mcp)
claude mcp add --transport http doitong-models https://api.doitong.com/v1/mcp \
--header "Authorization: Bearer $DOITONG_API_KEY"
# 2. Your agent calls the "run" tool with:
{
"model_id": "wan/v2.2-14b/speech-to-video",
"input": {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/avatar/talking_avatar.jpg",
"audio": "https://content.doitong.com/audio/showcase/v3/tools/dub_es.mp3"
}
}Call the Wan-2.2 Speech-to-Video 14B model (wan/v2.2-14b/speech-to-video) through the Doitong API. Docs for agents: https://doitong.com/developers/models/wan/v2.2-14b/speech-to-video.md
POST https://api.doitong.com/v1/run/wan/v2.2-14b/speech-to-video?wait=20
Authorization: Bearer $DOITONG_API_KEY
Content-Type: application/json
{
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/avatar/talking_avatar.jpg",
"audio": "https://content.doitong.com/audio/showcase/v3/tools/dub_es.mp3"
}
If the response status is "queued" or "running", poll GET https://api.doitong.com/v1/requests/REQUEST_ID?wait=20 until it is "succeeded"; the files are in outputs[].url. POST https://api.doitong.com/v1/quote/wan/v2.2-14b/speech-to-video with the same body returns the exact price before the run.Files like the example: $0.50 500 API credits your files are measured before the run Run it on this page
Your new API key. It is shown only now and is already in the code and in the API key field below. Keep it secret: never put it in code that runs in a browser.
Public works made with Wan v22 Large by the Doitong community. Reuse a prompt in one click.
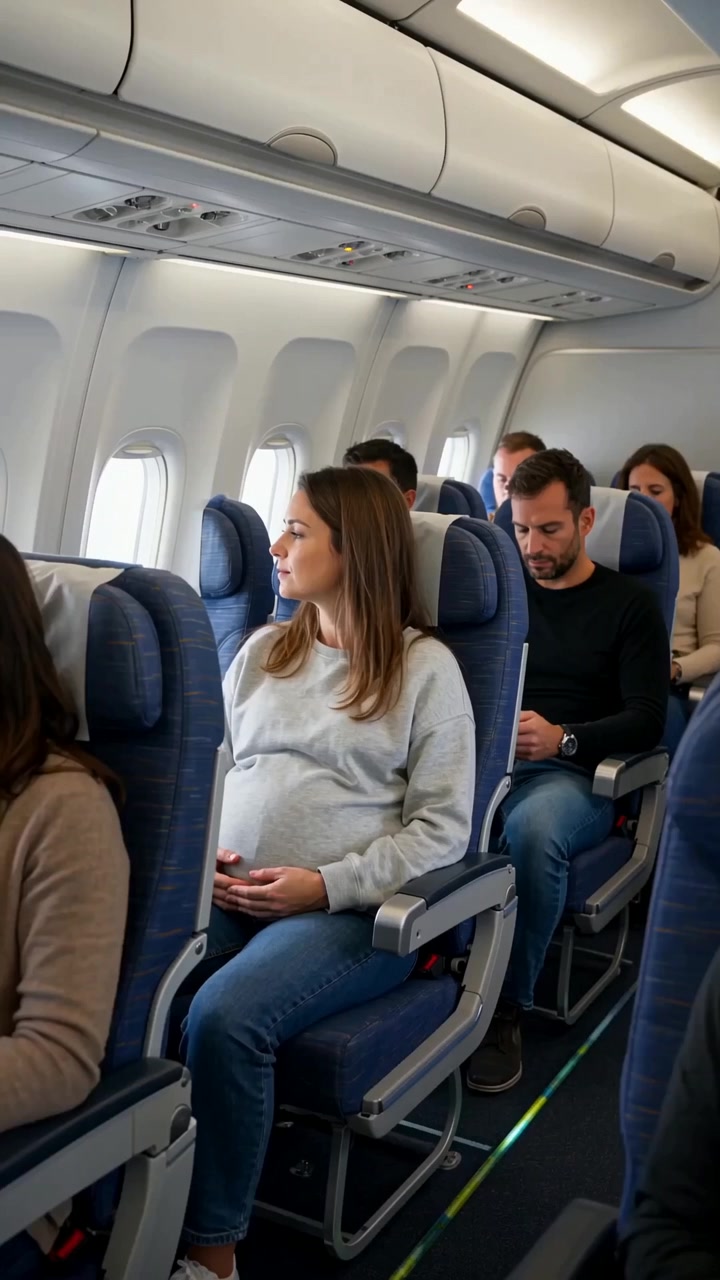 Video
Create a realistic cinematic UGC-style commercial video, exactly 30 seconds long. The entire scene takes place inside a modern passenger airplane during a daytime flight. Natural smartphone-like cinematography, realistic airplane cabin, authentic passengers, natural lighting, realistic skin...
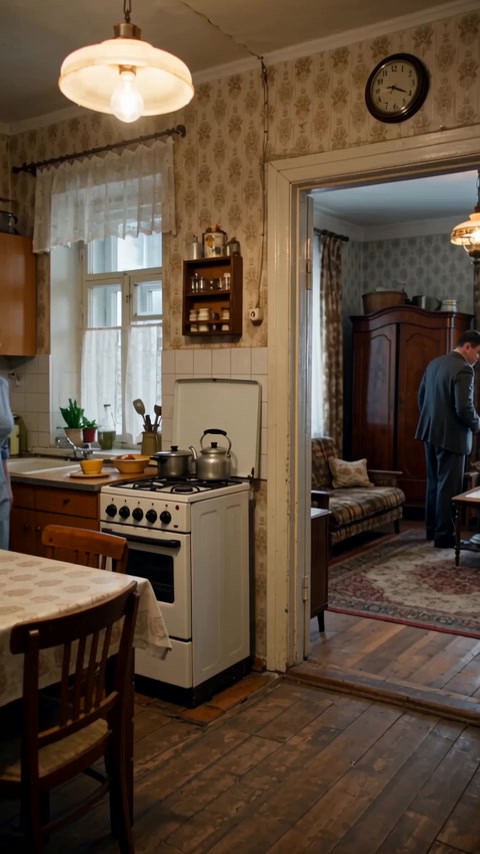 Video
Реалистичная бытовая сцена в советской одесской квартире зимним вечером. Женщина находится на кухне, мужчина — в комнате и прихожей. Атмосфера обычной советской семьи перед приходом гостей. Голоса: все персонажи говорят по-русски с естественным, выразительным одесским говором. Характерная...
Controls are generated from the model schema. The code and the price update as you change them.
/run/wan/v2.2-14b/speech-to-video?wait=20
quote → $0.50
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.com/v1/run/wan/v2.2-14b/speech-to-video?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
    "image": "https://content.doitong.com/images/showcase/v3/avatar/talking_avatar.jpg",
    "audio": "https://content.doitong.com/audio/showcase/v3/tools/dub_es.mp3"
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.com/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.com/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/wan/v2.2-14b/speech-to-video?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/avatar/talking_avatar.jpg",
"audio": "https://content.doitong.com/audio/showcase/v3/tools/dub_es.mp3"
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.com/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/avatar/talking_avatar.jpg",
"audio": "https://content.doitong.com/audio/showcase/v3/tools/dub_es.mp3",
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/wan/v2.2-14b/speech-to-video", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"]){
"jsonrpc": "2.0",
"id": 1,
"method": "tools/call",
"params": {
"name": "run",
"arguments": {
"model_id": "wan/v2.2-14b/speech-to-video",
"input": {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
"image": "https://content.doitong.com/images/showcase/v3/avatar/talking_avatar.jpg",
"audio": "https://content.doitong.com/audio/showcase/v3/tools/dub_es.mp3"
},
"wait_seconds": 20
}
}
}Your key stays in this browser: it is sent only to the Doitong API and saved (localStorage) only if you tick Remember. Get an API key
Needs a `prompt`, a source `image_url` and an `audio_url`, and produces a video of the pictured subject driven by the audio. `num_frames` runs from 40 to 120 in multiples of 4, at 16 fps by default. `resolution` can be 480p, 580p or 720p. Sampling steps, guidance, interpolation and a `negative_prompt` are adjustable.
Send either the canonical name or the native name, not both. Canonical names
promptrequired
negative_promptoptional
num_framesoptional
frames_per_secondoptional
seedoptional
resolutionoptional
num_inference_stepsoptional
enable_safety_checkeroptional
enable_output_safety_checkeroptional
guidance_scaleoptional
shiftoptional
video_qualityoptional
video_write_modeoptional
image_urlrequired
image
audio_urlrequired
audio
File parameters take a public https:// URL, a data: URI up to 10 MB, or the file_url of an upload. Files
{
  "id": "req_8k2m4q7x1z9c3v5b6n0p2r4t",
  "object": "request",
  "model": "wan/v2.2-14b/speech-to-video",
  "status": "succeeded",
  "created_at": "2026-10-20T12:00:00Z",
  "started_at": "2026-10-20T12:00:02Z",
  "completed_at": "2026-10-20T12:00:09Z",
  "queue_position": null,
  "cost": {
    "credits": 500,
    "usd": "0.50",
    "charged": 500,
    "refunded": 0
  },
  "input": {
    "prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
    "image_url": "https://content.doitong.com/images/showcase/v3/avatar/talking_avatar.jpg",
    "audio_url": "https://content.doitong.com/audio/showcase/v3/tools/dub_es.mp3"
  },
  "output": {
    "video": {
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.mp4",
      "content_type": "video/mp4",
      "file_name": "0-output.mp4",
      "file_size": 1843200
    }
  },
  "outputs": [
    {
      "type": "video",
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.mp4",
      "content_type": "video/mp4",
      "file_size": 1843200,
      "width": 1280,
      "height": 720,
      "duration": 5,
      "stored": true
    }
  ],
  "error": null,
  "metrics": {
    "inference_seconds": 6.8
  },
  "urls": {
    "self": "https://api.doitong.com/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t",
    "cancel": "https://api.doitong.com/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t/cancel"
  }
}For AI agents: this page as Markdown is at https://doitong.com/developers/models/wan/v2.2-14b/speech-to-video.md. All models and guides: https://doitong.com/developers/llms.txt