Video
Wan-2.2 Text-to-Video A14B Variants: 5
from $0.04 / second of output video
40 API credits / second of output video
No matches. Try “video”, “FLUX” or “webhooks”.
Loading models…
wan/v2.2-a14b/text-to-image
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.com/v1/run/wan/v2.2-a14b/text-to-image?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field"
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.com/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.com/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/wan/v2.2-a14b/text-to-image?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field"
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.com/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/wan/v2.2-a14b/text-to-image", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"])# 1. Connect once (Claude Code; Cursor, VS Code, Claude Desktop: https://doitong.com/developers/docs/mcp)
claude mcp add --transport http doitong-models https://api.doitong.com/v1/mcp \
--header "Authorization: Bearer $DOITONG_API_KEY"
# 2. Your agent calls the "run" tool with:
{
"model_id": "wan/v2.2-a14b/text-to-image",
"input": {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field"
}
}Call the Wan · v2.2 A14b · Text to Image model (wan/v2.2-a14b/text-to-image) through the Doitong API. Docs for agents: https://doitong.com/developers/models/wan/v2.2-a14b/text-to-image.md
POST https://api.doitong.com/v1/run/wan/v2.2-a14b/text-to-image?wait=20
Authorization: Bearer $DOITONG_API_KEY
Content-Type: application/json
{
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field"
}
If the response status is "queued" or "running", poll GET https://api.doitong.com/v1/requests/REQUEST_ID?wait=20 until it is "succeeded"; the files are in outputs[].url. POST https://api.doitong.com/v1/quote/wan/v2.2-a14b/text-to-image with the same body returns the exact price before the run.This request: $0.025 25 API credits Run it on this page
Your new API key. It is shown only now and is already in the code and in the API key field below. Keep it secret: never put it in code that runs in a browser.
Public works made with Wan v22 Large by the Doitong community. Reuse a prompt in one click.
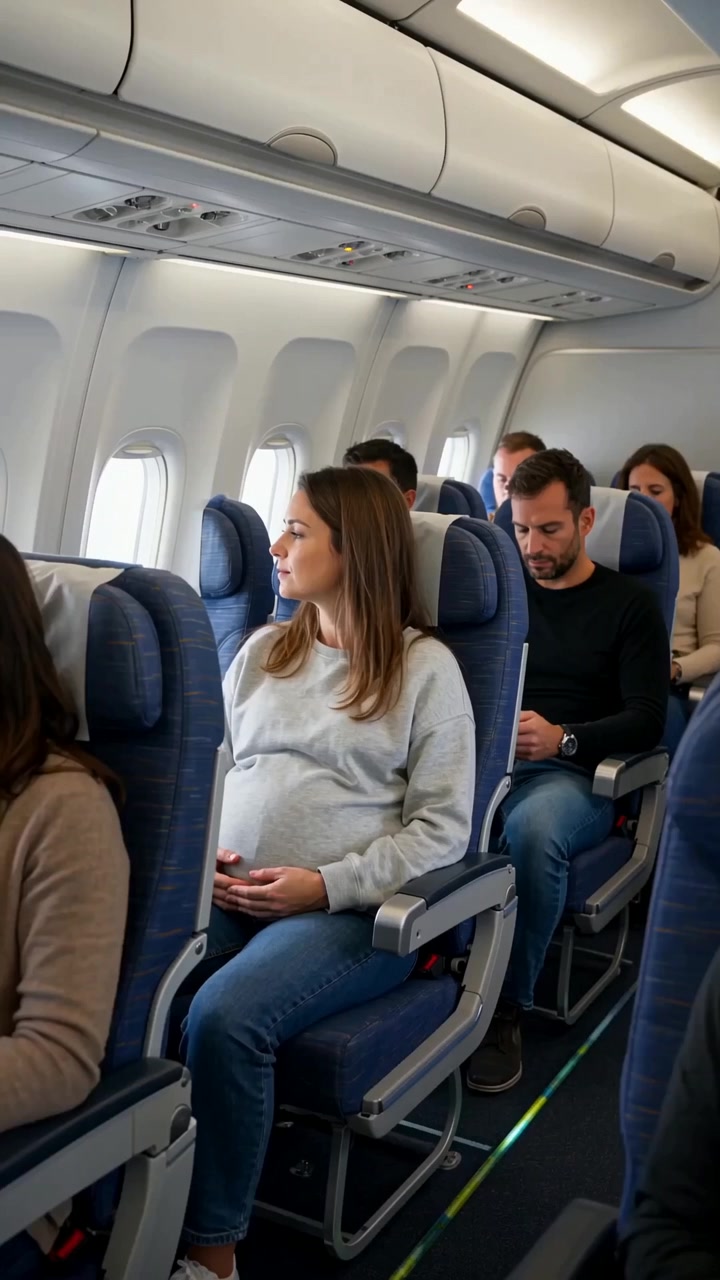 Video
Create a realistic cinematic UGC-style commercial video, exactly 30 seconds long. The entire scene takes place inside a modern passenger airplane during a daytime flight. Natural smartphone-like cinematography, realistic airplane cabin, authentic passengers, natural lighting, realistic skin...
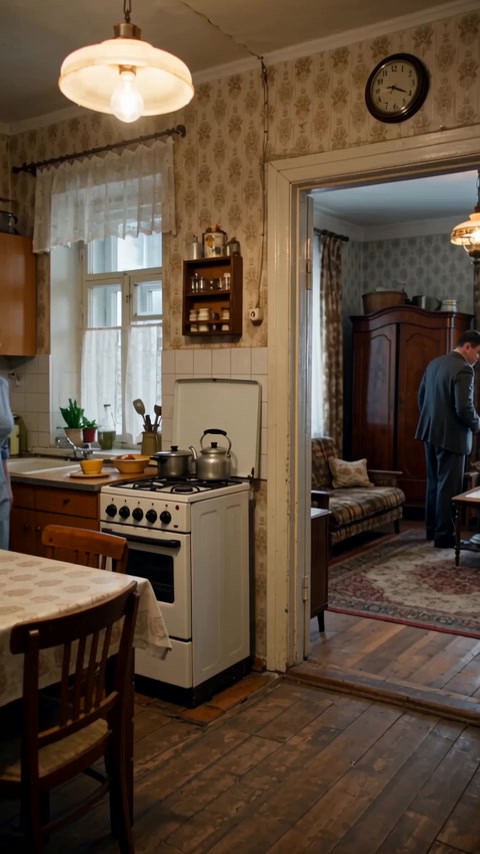 Video
Реалистичная бытовая сцена в советской одесской квартире зимним вечером. Женщина находится на кухне, мужчина — в комнате и прихожей. Атмосфера обычной советской семьи перед приходом гостей. Голоса: все персонажи говорят по-русски с естественным, выразительным одесским говором. Характерная...
Controls are generated from the model schema. The code and the price update as you change them.
/run/wan/v2.2-a14b/text-to-image?wait=20
quote → $0.025
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.com/v1/run/wan/v2.2-a14b/text-to-image?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field"
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.com/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.com/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/wan/v2.2-a14b/text-to-image?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field"
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.com/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field",
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/wan/v2.2-a14b/text-to-image", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"]){
"jsonrpc": "2.0",
"id": 1,
"method": "tools/call",
"params": {
"name": "run",
"arguments": {
"model_id": "wan/v2.2-a14b/text-to-image",
"input": {
"prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field"
},
"wait_seconds": 20
}
}
}Your key stays in this browser: it is sent only to the Doitong API and saved (localStorage) only if you tick Remember. Get an API key
Produces a still image from a text `prompt` with the larger A14B model. `image_size` offers square, portrait and landscape presets. Besides `guidance_scale`, a second-stage `guidance_scale_2` is available, along with `num_inference_steps` (2 to 40), `shift`, `negative_prompt` and an `acceleration` choice of none or regular.
promptrequired
negative_promptoptional
seedoptional
num_inference_stepsoptional
enable_safety_checkeroptional
enable_output_safety_checkeroptional
enable_prompt_expansionoptional
accelerationoptional
guidance_scaleoptional
guidance_scale_2optional
shiftoptional
image_sizeoptional
{
  "id": "req_8k2m4q7x1z9c3v5b6n0p2r4t",
  "object": "request",
  "model": "wan/v2.2-a14b/text-to-image",
  "status": "succeeded",
  "created_at": "2026-10-20T12:00:00Z",
  "started_at": "2026-10-20T12:00:02Z",
  "completed_at": "2026-10-20T12:00:09Z",
  "queue_position": null,
  "cost": {
    "credits": 25,
    "usd": "0.025",
    "charged": 25,
    "refunded": 0
  },
  "input": {
    "prompt": "A red fox trots through fresh snow at sunrise, soft golden light, shallow depth of field"
  },
  "output": {
    "image": {
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.jpeg",
      "content_type": "image/jpeg",
      "file_name": "0-output.jpeg",
      "file_size": 1843200
    },
    "seed": 42
  },
  "outputs": [
    {
      "type": "image",
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.jpeg",
      "content_type": "image/jpeg",
      "file_size": 1843200,
      "width": 1024,
      "height": 768,
      "stored": true
    }
  ],
  "error": null,
  "metrics": {
    "inference_seconds": 6.8
  },
  "urls": {
    "self": "https://api.doitong.com/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t",
    "cancel": "https://api.doitong.com/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t/cancel"
  }
}
For AI agents: this page as Markdown is at https://doitong.com/developers/models/wan/v2.2-a14b/text-to-image.md. All models and guides: https://doitong.com/developers/llms.txt